Open models. Local compute. Predictable cost
Hyperfusion provides production inference and training infrastructure in the UAE, offering high-performance, compliant, and OpenAI-compatible API access with pricing you can forecast before you ship.
We are the infrastructure layer for AI teams that need performance, cost control, and regional alignment with their users.
AI infrastructure still has a geography problem.
Models are open. Research is public.
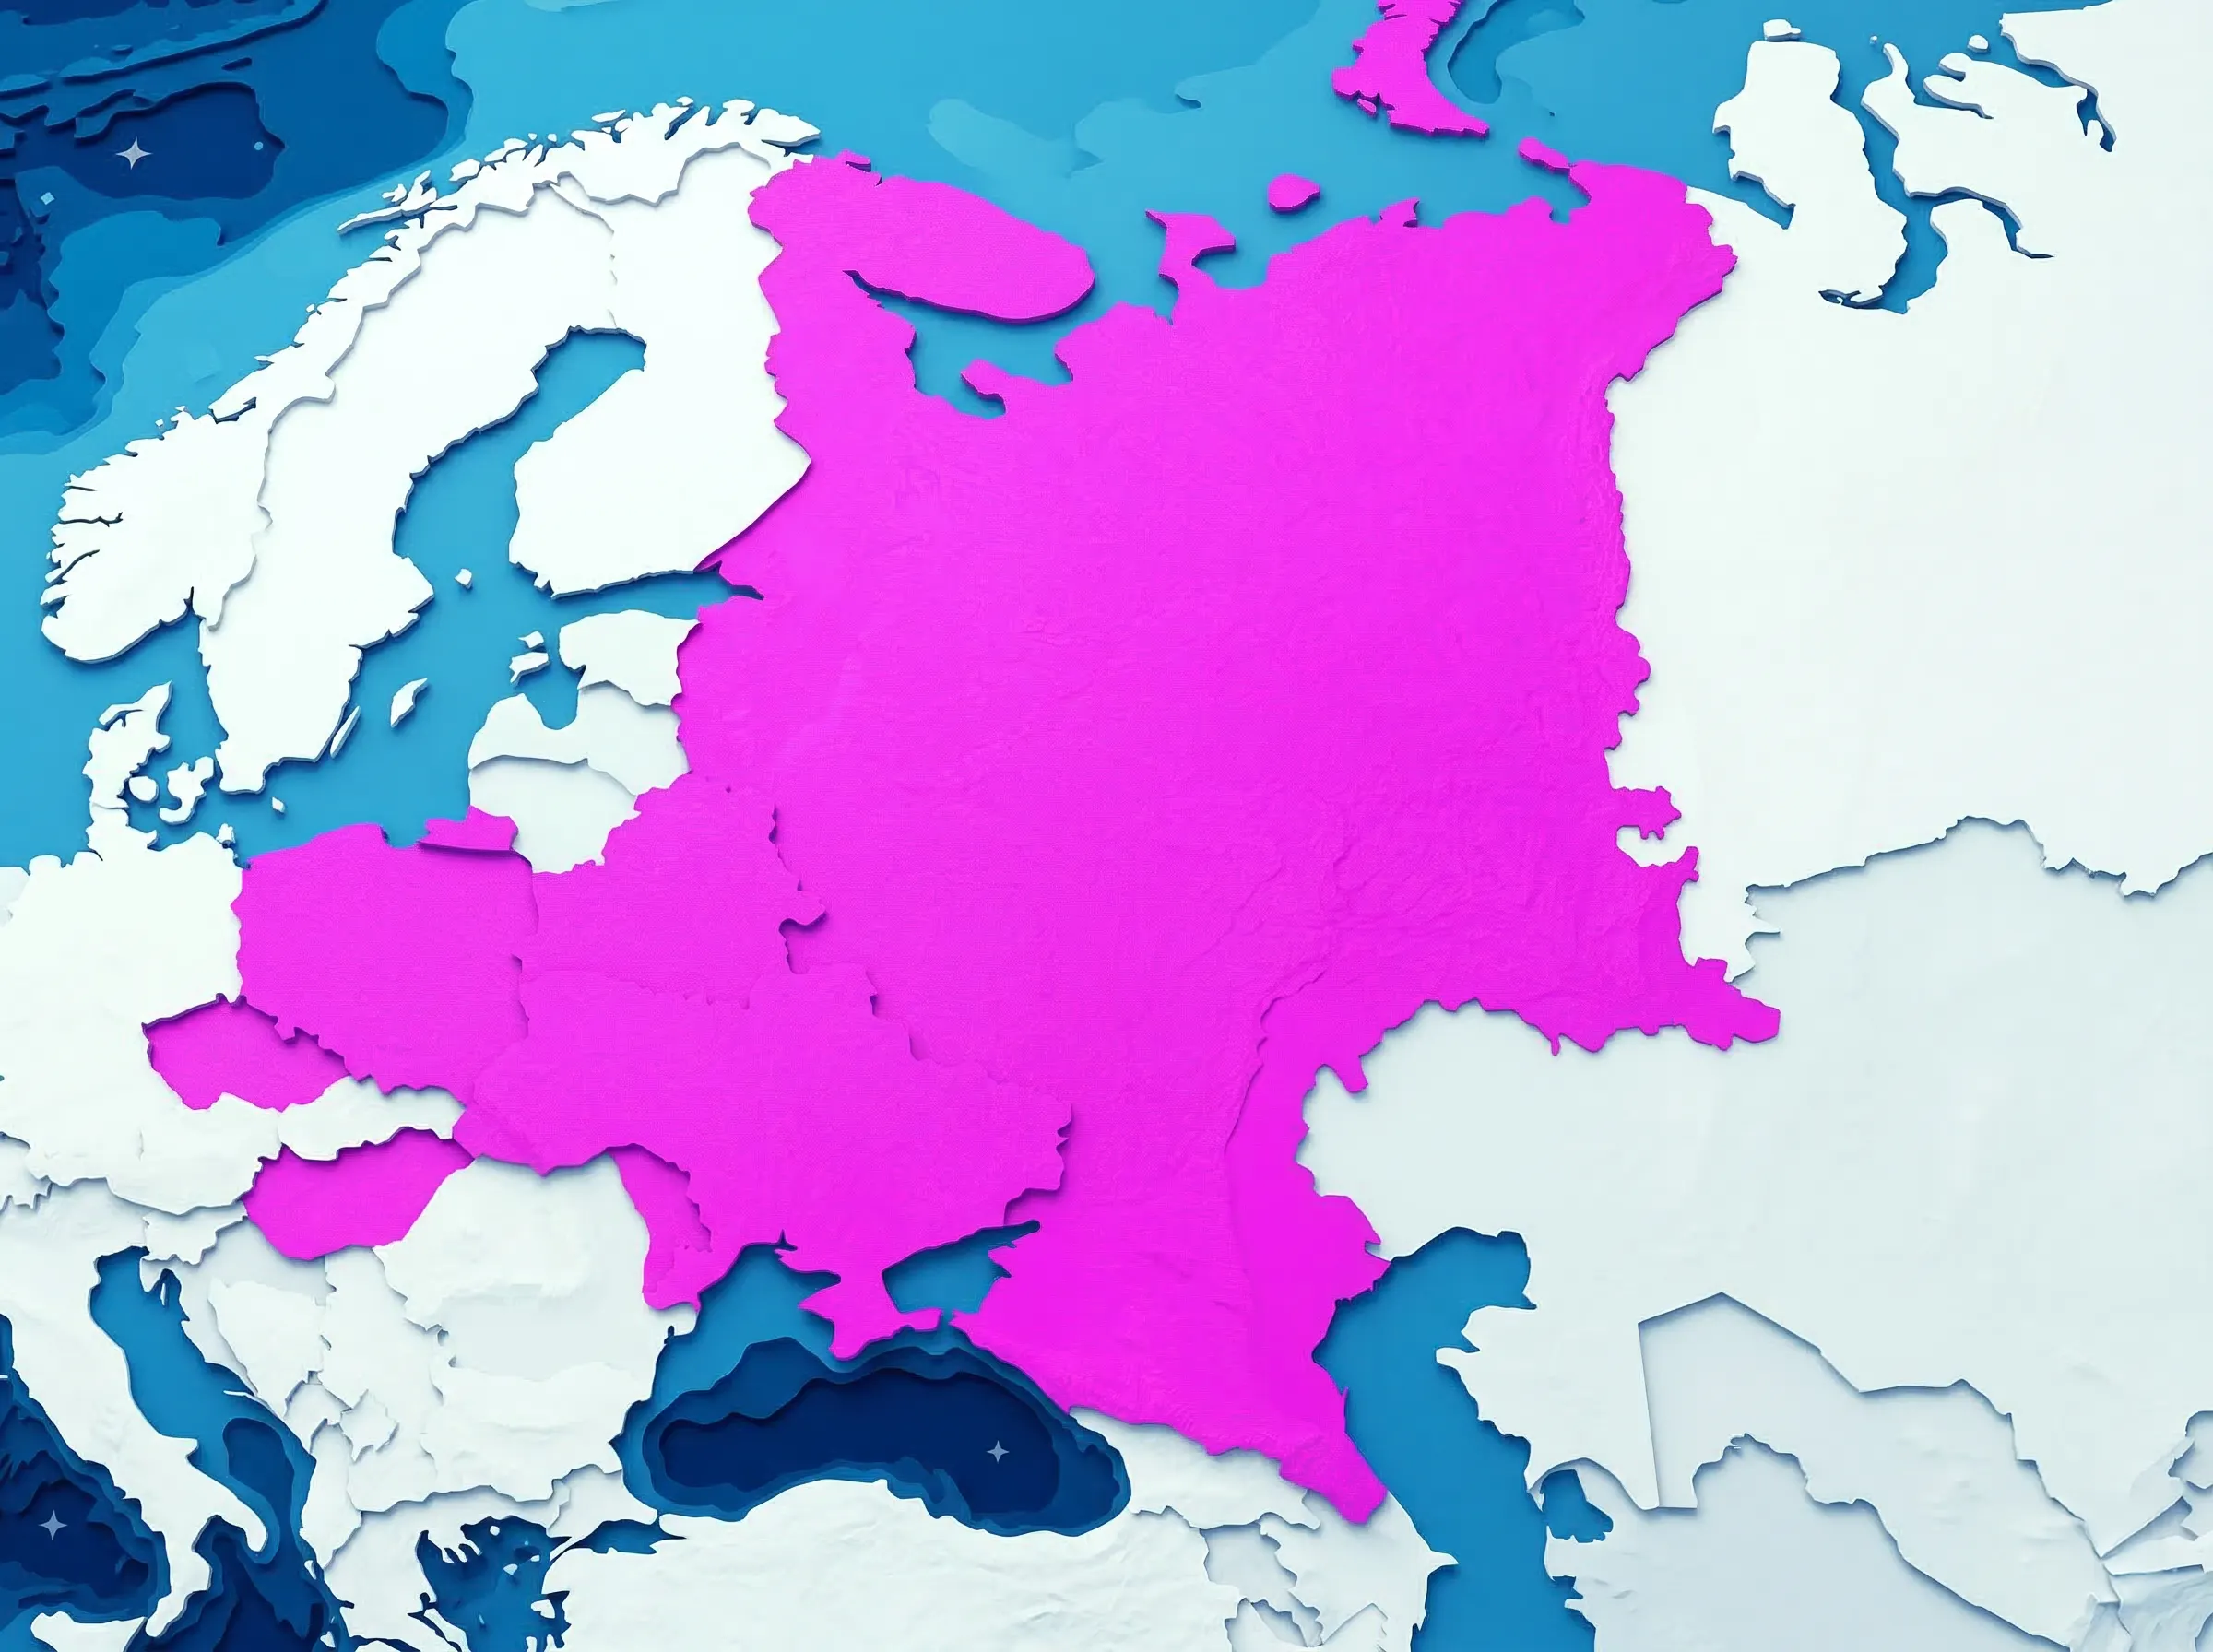
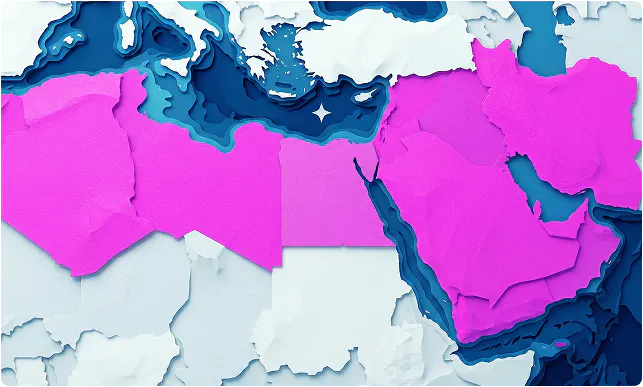
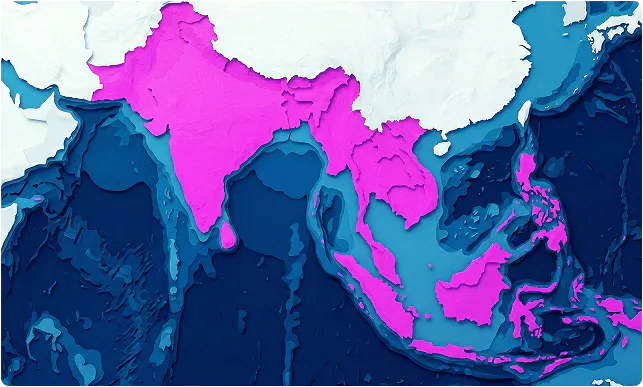
But most high-performance compute remains concentrated in the US and EU, creating latency, inflated costs, and compliance pains for teams serving users across Eastern Europe, the Middle East, and South Asia.
We built Hyperfusion to address that gap.
Models are open. Research is public.
But most high-performance compute remains concentrated in the US and EU, creating latency, inflated costs, and compliance pains for teams serving users across Eastern Europe, the Middle East, and South Asia.
We built Hyperfusion to address that gap.

NVIDIA H100, H200 and B300 GPU clusters (Vera Rubin coming soon) hosted in UAE Tier 3 data centers

Predictable, outcome-based pricing designed for production workloads

OpenAI-compatible APIs to minimise migration effort

Production infrastructure hosted within the GCC region
Local by design
AI infrastructure should be close to the users it serves and designed for their needs.
We deploy GPU clusters close to users in MENA and the Indian subcontinent so developers can reduce latency, meet data residency requirements, and support sovereign AI initiatives.
Predictable and outcome-based
AI costs should be forecastable. Bill-shock kills innovation (and companies). We structure pricing around defined workloads and outcomes rather than volatile token-based billing that creates uncertainty for finance teams.
Built for ownership
Your models. Your data. Your control.
We support zero-retention inference under enterprise plans and single-tenant isolation, allowing teams to maintain control over infrastructure and compliance posture.
Built by engineers, for engineers.
The next wave of AI products will not be built in one geography alone.
We’re empowering Warsaw, Dubai, Bangalore, Jakarta, Bucharest, and Riyadh engineers who understand their markets and regulatory environments and want to build quickly and affordably.
We believe predictable, outcome-based pricing is the only alternative to volatile usage-based billing.
We are building toward a world where a five-person startup in Bucharest, a regulated fintech in Riyadh and a government department in Abu Dhabi have access to the same class of GPU infrastructure as teams operating in major US cloud regions.
We deliver:
GPU clusters deployed in strategically relevant regions
Drop-in compatibility with widely used APIs such as OpenAI
Transparent pricing models that can be forecast
A support team that understands production AI systems

Your users are here. So are we.
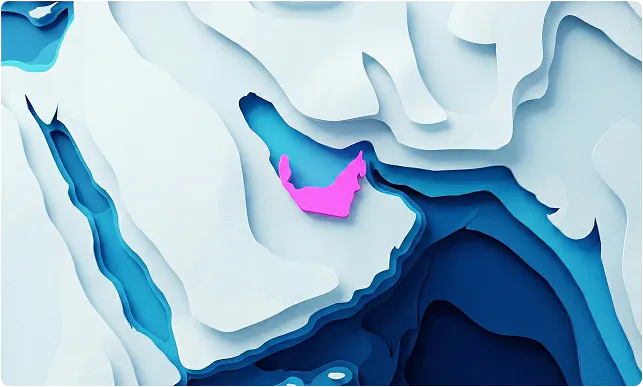
United Arab Emirates
Primary Infrastructure Location
Our infrastructure is hosted in UAE Tier 3 data centers on NVIDIA H100, H200 and B300 GPUs (Vera Rubin coming soon) with InfiniBand interconnect for multi-GPU workloads. Controls are designed in accordance with ISO 27001 standards. Production workloads are hosted within the GCC region.
Typical latency to major Gulf, South Asia, and Eastern European hubs is generally under 50ms, depending on routing conditions.
Ship AI-powered products faster.
Our inference API provides access to state-of-the-art open-weight models optimised for speed, cost, and scale.
Teams use Hyperfusion to build:
Production-grade chatbots, multilingual assistants, and customer support automation with real-time streaming and multi-turn memory.
AI copilots for IDEs, internal tooling, and CI/CD workflows using OpenAI-compatible endpoints.
Multi-step AI agents that reason, call tools, and execute structured tasks end-to-end.
Knowledge assistants, semantic search systems, and document Q&A grounded in private data.
Models optimised for structured reasoning, planning, and analytical workloads.
Image generation, multimodal analysis, document parsing, and speech-to-text processing.
Reliable structured outputs for entity extraction, classification, and workflow automation.
Domain-specific model training without managing GPUs.
Dedicated infrastructure, zero-retention options, and compliance-aligned hosting for regulated industries and public sector teams.
Built on leading open-weight models.

gpt-oss-120b (OpenAI, Apache 2.0, 117B params / 5.1B active MoE, reasoning-focused)
gpt-oss-20b (OpenAI, Apache 2.0, 21B params / 3.6B active)

Qwen3.8-27B (Alibaba, 27B dense, text + image input)

Gemma 4 31B (Google, 31B, text + image input)

DeepSeek-V4-Flash (DeepSeek, fast general-purpose model)
Your data stays within the region.
Your compliance posture stays intact.
We support teams operating in regulated industries and public sector environments.
Infrastructure
- NVIDIA H100, H200 and B300 GPUs (Vera Rubin coming soon) hosted in UAE Tier 3 data centers
- InfiniBand interconnect for high-throughput workloads
- Role-Based Access Control (RBAC)
- AES-256 encryption at rest
- TLS 1.3 encryption in transit
- Single-tenant GPU isolation under enterprise plans.
Compliance & Governance
- Controls designed in accordance with ISO 27001 standards
- SOC 2 Type II in progress
- HIPAA-ready deployment models under enterprise agreements
- Production inference workloads hosted within the GCC region
- No cross-border transfer of inference data
- BYOC options for sovereign cloud commitments.
Data Retention Policy
Under enterprise plans:
NVIDIA H100, H200 and B300 GPUs (Vera Rubin coming soon) hosted in UAE Tier 3 data centers
- Zero retention for inference payloads
- Prompts and outputs are not stored or used for training
- Operational metadata logging excludes inference content
Detailed controls documentation available upon request.

Our outcome-based pricing model is designed for production inference workloads.
Instead of billing solely on GPU runtime or token usage, pricing aligns to defined workload outputs and performance targets. Finance teams can forecast costs before deployment.
Detailed pricing frameworks are shared during project scoping.
Don’t wait. Start now.
Generate your API key and make your first inference call in minutes.
Or describe your project and receive structured pricing before committing.
Market Intel
Get GPU market and model usage insights to your inbox.